Most content teams don’t fail at scaling because they publish too much. They fail because they compress the wrong things first — and they do it before they even realize the system is breaking. Research briefs get thinner. Editorial review collapses into a spell-check pass. Topic selection drifts toward keyword density instead of genuine intent fit. The output volume goes up. The quality quietly goes down.
Content scaling — the real kind, not the volume-chasing version — is an operational problem. It is not solved by hiring a fifth writer or buying another AI tool. It is solved by building a system that encodes editorial standards into every production stage, so that quality is a structural output of the process rather than a heroic individual effort applied at the end. This article gives you that system: a precise operational definition, a self-diagnostic maturity model, a clear framework for what to automate versus what to protect, and a practical publishing workflow for small WordPress teams ready to increase output without sacrificing the research quality, editorial judgment, and brand voice that make content worth reading — and worth ranking.
Key Takeaways: Content Scaling
- It's a systems problem: Content scaling is the operational discipline of expanding production capacity while preserving editorial standards — not a publishing-frequency target or a headcount decision.
- Quality erodes in sequence: The Compression Cascade shows that topic selection degrades first under volume pressure, then research depth, then editorial angle, then fact-checking — each stage making the next failure more likely.
- Automate friction, protect judgment: Formatting, scheduling, brief population, and WordPress publishing are safe to automate. Intent interpretation, source credibility evaluation, claim verification, and brand voice calibration are not.
- Use the maturity model: Four stages — Manual and Reactive, Templated and Brief-Driven, Workflow-Automated, Measured and Optimized — give you a self-diagnostic and a single priority action per stage.
- Google's standard is non-negotiable: According to Google's own documentation, content that is mass-produced without individual page care is an explicit quality negative in their ranking evaluation — helpfulness and reliability are the durable standard, regardless of production method.
What Content Scaling Actually Means (And What It Doesn’t)
Content scaling is the systematic expansion of editorial production capacity without a proportional increase in cost, headcount, or quality degradation. That definition is deliberate. “More articles per week” is a volume target. It is not a scaling strategy. A volume target without an operational system is a stress test — one that reliably exposes every weak point in your editorial process, usually at the worst possible moment.
Two specific misreadings get in the way here. The first is conflating content scaling with raw publishing velocity: the belief that getting to 20 pieces a month from 8 is, itself, the goal. It isn’t. The goal is building a system where 20 quality pieces per month is the repeatable output — and where you could get to 30 without the editorial standards collapsing. The second misreading is conflating content scaling with programmatic content. Programmatic SEO scales pages through templates, structured data, and database-driven generation — a different mechanism with a different risk profile and a different use case. The two overlap at the infrastructure layer, but they are distinct strategies. If you are building editorial content that requires research, original analysis, and brand voice, you are in the content scaling domain, not the programmatic SEO domain.
The professional vocabulary for what you are building is ContentOps — treating content production as a repeatable operational function with defined inputs, measurable outputs, quality gates, and a feedback loop. This is the discipline that separates teams that scale successfully from teams that scale until something breaks.
The Compression Cascade: How Quality Erodes Before You Notice It
Here is the most underdiagnosed failure pattern in content scaling: quality doesn’t collapse all at once. It erodes sequentially, one production stage at a time, and each stage’s failure makes the next one more likely. This is the Compression Cascade — and understanding it changes how you diagnose underperformance.
The cascade almost always starts at topic selection. Volume pressure pushes teams toward head terms with high search volume but misaligned intent — keywords that look attractive in a spreadsheet but don’t match what the reader actually needs at that moment in their decision process. High bounce rates follow. Then rankings for the wrong queries. The damage here compounds downstream because a misaligned topic produces a misaligned brief, which produces a misaligned article. The second stage to erode is research depth. Briefs get thinner because there’s less time. Source verification gets skipped. Claims get sourced from secondary aggregators instead of primary sources. Google’s quality evaluation framework explicitly asks whether content “provides original information, reporting, research, or analysis” and whether it “avoids simply copying or rewriting those sources.” When research compresses, both answers move toward “no” — quietly, one article at a time.
The middle stages follow predictably. The editorial angle disappears: briefs default to “cover everything” without a distinctive thesis, producing competent summaries that fail to differentiate from the ten existing articles already ranking for the same term. Review collapses into proofreading. Factual errors and unsupported claims survive to publish. Internal linking becomes mechanical — inserted for coverage rather than contextual fit. The diagnostic signal that tells you a cascade is underway is this: if your published output looks individually acceptable but underperforms collectively, the problem started upstream — likely at topic selection or brief quality — not in the writing itself.
| Production Stage | Quality Signal That Erodes First | Early Warning Indicator | Consequence at Scale |
|---|---|---|---|
| Topic Selection | Intent specificity | Articles target head terms with misaligned intent | High bounce rates; ranking for wrong queries |
| Research | Source authority and verification | Claims sourced from aggregators, not primary sources | Factual errors; E-E-A-T degradation |
| Brief Creation | Angle differentiation | Briefs default to covering everything without a thesis | Generic content that fails to rank |
| Drafting | Depth of insight | Sections summarize existing content; no original analysis | Content lacks Information Gain; treated as thin |
| Editorial Review | Claim accuracy check | Review becomes structural/stylistic only | Errors and unsupported claims published |
| Publishing | Internal link relevance | Links inserted for coverage, not contextual fit | Topical coherence degrades |
| Measurement | Performance attribution | Traffic tracked but not attributed to content decisions | No feedback loop — scaling continues blindly |
Automation Should Remove Friction, Not Judgment
This is the central operating principle of any scaling system that works. It is also the most frequently violated one. Teams automate the wrong layer — not because they don’t care about quality, but because the line between friction and judgment is genuinely blurry until you map it explicitly.
Friction tasks are repeatable, rule-based, and have a right answer that doesn’t depend on context: formatting a draft to match your WordPress template, populating a brief’s structural fields from a keyword, scheduling a published post, resizing a featured image, assigning a category. These are safe to automate. The cost of automation is low; the benefit is real. Judgment tasks are different. Interpreting search intent requires understanding what the reader is actually trying to do, not just what they typed. Evaluating source credibility requires knowing what distinguishes a trustworthy primary source from a well-formatted aggregator. Verifying a claim requires checking it against reality, not against another article’s assertion. Brand voice calibration requires a feel for tone that no checklist fully captures. These cannot be safely automated — not because AI tools are incapable of producing plausible-sounding output in these areas, but because the plausibility of the output is precisely what makes the failure mode dangerous.
Google’s AI content guidance is explicit on this point: “using generative AI tools or other similar tools to generate many pages without adding value for users may violate Google’s spam policy on scaled content abuse.” The critical phrase is “without adding value.” An AI can draft a structurally correct article that sounds authoritative and is factually wrong, contextually misaligned, or brand-voice-neutral. Automating the judgment layer doesn’t produce bad-looking content — it produces content that looks fine and performs badly. That’s the harder failure mode to catch.
| Task Category | Specific Task | Safe to Automate? | Risk If Automated Without Oversight |
|---|---|---|---|
| Topic & Strategy | Keyword research data pull | Yes | Low |
| Topic & Strategy | Search intent interpretation | No — Human judgment | Misaligned content targeting wrong query type |
| Topic & Strategy | Angle selection for competitive SERPs | No — Human judgment | Generic, undifferentiated positioning |
| Research | Source discovery / SERP scanning | Yes | Low |
| Research | Source credibility evaluation | No — Human judgment | Low-authority claims go unchecked |
| Research | Claim verification / fact-checking | No — Human judgment | Factual errors published at scale |
| Drafting | Brief population from template | Yes | Low |
| Drafting | First-draft generation from brief | Partial (with review gate) | Generic output published without editorial pass |
| Drafting | Brand voice calibration | No — Human judgment | Tonal drift across the content library |
| Editorial | Structural review (headers, flow) | Partial | Low if checklist-driven |
| Editorial | Depth and originality assessment | No — Human judgment | Thin content passes review undetected |
| Publishing | WordPress formatting and scheduling | Yes | Low |
| Measurement | Performance data aggregation | Yes | Low |
| Measurement | Diagnosing underperformance root cause | No — Human judgment | Wrong optimization action applied |
The Content Scaling Maturity Model: Where Is Your Team Right Now?
No scaling framework is useful if it can’t tell you where you currently are. This four-stage model is designed as a self-diagnostic tool, not a hierarchy to feel bad about. Read the table, identify your stage, and focus on the single priority action for that stage before doing anything else.
| Element | Stage 1 | Stage 2 | Stage 3 | Stage 4 |
|---|---|---|---|---|
| Name | Manual & Reactive | Templated & Brief-Driven | Workflow-Automated | Measured & Optimized |
| Operational reality | Each article produced from scratch; no repeatable process; topic selection is ad hoc | Content briefs standardize structure; research guided but still manual; editorial review informal | Tooling handles formatting, scheduling, brief population; AI supports drafting; humans own judgment gates | Every article tracked to performance metrics; topical gaps drive new content; underperformance triggers structured audits |
| Primary bottleneck | Writer bandwidth — no leverage exists anywhere | Research and review compress first when volume pressure grows | Measurement is absent — output grows but impact is unmeasured | Sustaining editorial standard as team or contributor pool grows |
| Quality risk | Inconsistent depth and voice across articles | Consistent in structure but not in depth or accuracy | AI-assisted drafts bypass editorial review because “we have a system now” | Dilution of standards when new contributors onboard without training |
| Priority action | Document your existing best process into a single repeatable brief template | Add a structured review checklist with specific quality signals per production stage | Build a publishing QA gate: no article publishes without passing a minimum editorial checklist | Create a contributor onboarding system tied to brand voice, research standards, and QA protocols |
Stage 1 is where most solo bloggers and new content teams operate. Every article is a bespoke effort. There is no leverage anywhere in the system. The priority action is not to add tools — it is to document what you already do when you produce your best work, and turn that into a reusable brief template. That template is the foundation everything else is built on.
Stage 2 is where a surprising number of established teams get stuck. The briefs exist. The process looks repeatable. But when volume pressure grows — a product launch, an editorial calendar push — research and review are the first things to compress. The priority action here is to make the review stage explicit: a checklist with named quality signals at each production stage, assigned to a specific person, before publishing.
Stage 3 is where automation enters the picture. Tools handle the friction layer. AI supports first drafts. But Stage 3 teams consistently make the same mistake: they add tooling without adding a corresponding quality gate, and the system starts treating plausible AI output as review-ready output. The priority action is a hard publishing gate — no article publishes without a named editor confirming that the judgment-layer checklist has been completed. Stage 4 is a measurement and optimization operation. If you are reading this article for the first time, you are almost certainly at Stage 1 or Stage 2. That’s the right starting point.
Building the Editorial System: Strategy, Research, and Briefs at Scale
The brief is the most leveraged artifact in a content scaling system. A well-built brief does more editorial work than almost any other investment you can make. It encodes search intent, required sources, editorial angle, audience framing, and brand voice notes before a word of content is written. If the brief is right, the quality floor of every subsequent draft — human or AI-assisted — rises significantly. If the brief is thin, no amount of post-draft editing recovers the article fully.
Topic selection within a scaling system should be driven by keyword clustering and explicit intent classification, not by keyword volume alone. Group related terms by the underlying question they represent, assign each cluster to a specific content format (definitive guide, comparison, tactical how-to, opinion piece), and sequence the editorial calendar to build topical authority around those clusters rather than scattering individual articles across unrelated topics. This is the difference between publishing content and building a content asset. For teams using AI in their workflow, writing SEO articles with AI requires this kind of structured upstream thinking — the quality of the AI output is directly constrained by the quality of the input brief.
Content velocity — how fast pieces move from brief to published — is a useful diagnostic metric at this stage, but only as a signal, not a goal. If velocity slows at the research stage, the research process is the bottleneck: either the brief doesn’t surface sources efficiently, or the fact-checking step lacks a defined protocol. If velocity slows at the review stage, the review process is either under-resourced or undefined. Track velocity by stage, not just by total cycle time, and you get a map of where to invest next.
AI as Infrastructure, Not Author
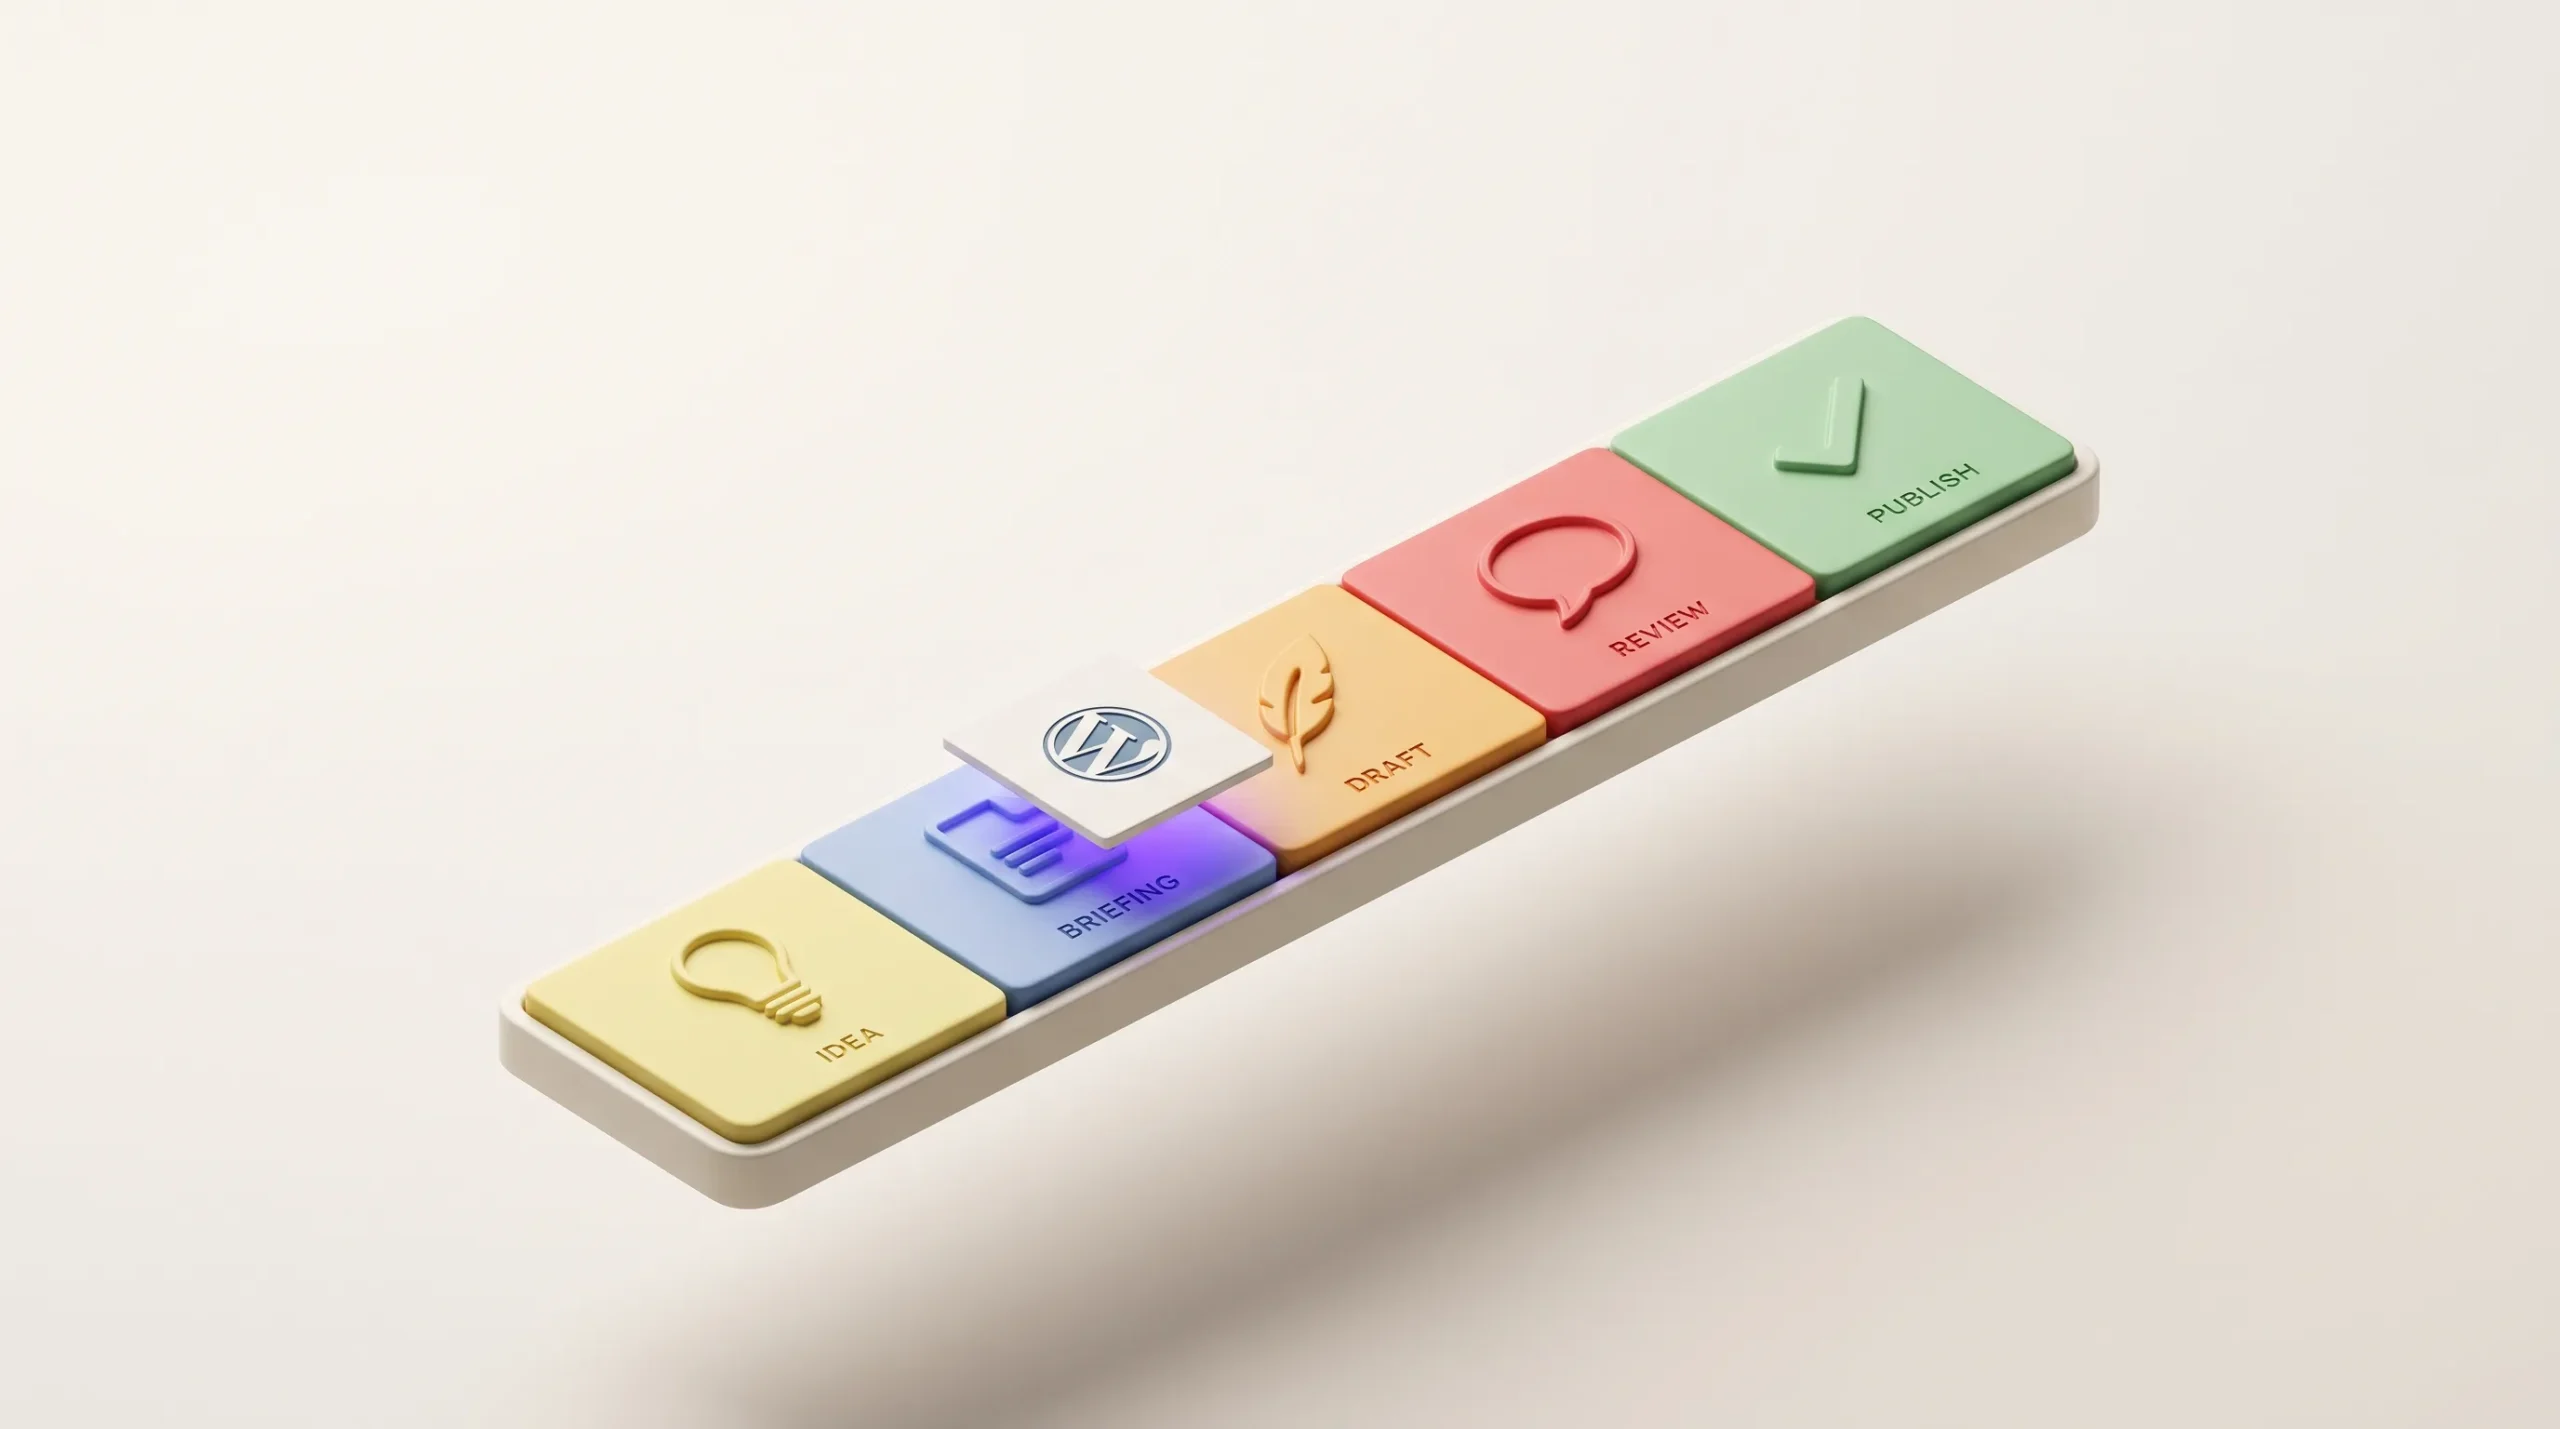
The framing that works for AI in a scaling system is infrastructure, not authorship. AI handles research synthesis — summarizing source sets, surfacing PAA clusters, populating brief fields from a keyword — and first-draft scaffolding: structure, factual skeleton, and heading architecture. Human editorial work remains responsible for intent fit, original analysis, brand voice, claim verification, and final judgment calls. That’s the division that produces content worth reading.
Google’s guidance on AI-generated content makes the standard clear: accuracy, quality, and relevance are the requirements, regardless of production method. The objection is not to AI-assisted content — it is to AI-generated content that does not add value. Google’s spam policies name “scaled content abuse” explicitly as a policy violation, covering “techniques used to deceive users or manipulate Search systems.” Generating volume without editorial judgment is the behavior that triggers this — not the use of AI itself. This distinction matters for how you position AI in your workflow: it is a production accelerator for the friction layer, not a replacement for the editorial layer.
The AI content case study at Contentosapp — 25 articles in 25 days on WordPress illustrates what AI-supported scaling looks like at the operational level. The honest framing: results depend on the quality of the system around the AI, not the AI alone. If the brief is weak, if the review gate is missing, if the intent interpretation is delegated to the model — the output reflects those gaps. Use AI to make content rank by treating it as one component of a larger editorial system, not as the system itself.
Automate
Protect — Human Judgment
The productivity gain from AI in content production is real — but it accrues only when the division of labor is explicit: automation owns the repeatable, humans own the irreplaceable.
The WordPress Publishing Workflow: Automating the Last Mile Without Losing Control
The publishing stage is where small teams lose the most time to manual friction — and where automation has the highest return because it involves zero editorial judgment. Every minute spent manually copying metadata, assigning categories, attaching a featured image, and clicking “schedule” is a minute not spent on research or review. These tasks are mechanical, rule-based, and fully automatable.
A practical WordPress publishing SOP for a scaling content team should cover:
- Metadata completion: title tag, meta description, and Open Graph fields populated before scheduling
- Category and tag assignment aligned to your topical cluster structure
- Featured image attached and alt text written with the target keyword
- Internal links confirmed (surfaced during brief creation, approved during editorial review)
- Schema markup applied where relevant (Article, HowTo, FAQ)
- Canonical URL set for any repurposed or syndicated content
- Scheduled publish time set against your editorial calendar
- Post-publish check: indexed correctly, no rendering issues, internal links resolving
For teams ready to automate the publishing handoff programmatically, the WordPress REST API provides the infrastructure layer. As the official documentation states, it “provides an interface for applications to interact with your WordPress site by sending and receiving data as JSON objects” — meaning you can push formatted content, metadata, and scheduling instructions from an external application directly into WordPress without manual intervention. This is a Stage 3 capability. It is not the first thing to build — get the brief template and review checklist right first. But for teams that have those foundations in place, API-driven publishing is where the remaining manual friction disappears. Contentosapp Studio handles this publishing layer natively for WordPress-based operations, removing the need for custom API development on smaller teams.
Common Scaling Failure Modes (And How to Catch Them Early)
The failure modes that kill scaling efforts are predictable. They appear in a consistent order, and each has a detectable early signal — before it shows up in traffic data or ranking drops, which is the expensive moment to catch it.
Volume targets set before systems exist. The team commits to 20 articles a month before a repeatable brief template, a review protocol, or a defined research process is in place. The volume target forces the compression cascade immediately. Early signal: cycle time is irregular — some pieces take days, others take a week, with no obvious reason for the variance.
Brief quality degrades before draft quality degrades. This is the leading indicator no one watches. When briefs get thinner — less specific intent framing, fewer required sources, no angle guidance — the drafts that follow look fine individually but underperform collectively. Early signal: review edits cluster around “this doesn’t have a clear point of view” rather than structural or factual corrections.
Review gates collapse first under deadline pressure. The editorial review stage is the most expensive in terms of senior time, so it’s the first to be shortcut when a deadline is tight. Early signal: the editor role shifts from “final judgment” to “last set of eyes before publishing” — a status check rather than a quality gate.
Internal linking treated as optional. Links inserted for coverage rather than contextual fit, or skipped entirely when there’s no obvious candidate. Early signal: your topical cluster pages don’t reference each other in ways that reinforce the cluster’s authority.
Content velocity measured; content quality not. The team tracks how many pieces published per month and calls that the scaling metric. Performance impact is assumed, not measured. Early signal: output is growing but organic traffic is flat or declining on a per-piece basis.
Scaling Readiness Checklist
- Do you have a documented content brief template that encodes your editorial standards?
- Is there a named person responsible for final editorial review on every piece?
- Do you have a process for verifying factual claims before publishing?
- Is topic selection driven by intent classification, not just keyword volume?
- Do you track content velocity by production stage (not just total cycle time)?
- Is your internal linking process defined, not ad hoc?
- Do you measure content performance at 90 days, not just at publish?
- Can a new contributor produce a brief-quality piece without asking you how?
How to Measure Whether Your Content Scaling System Is Actually Working
Measurement is what separates Stage 3 from Stage 4. Without it, you are scaling output, not scaling performance — and those are different problems with different solutions. The metrics that matter fall into two categories: volume metrics and quality metrics. Teams that only track the former are running a publishing schedule, not a scaling system.
Volume metrics tell you how much you published: pieces per period, cycle time from brief to publish, number of topics in the active pipeline. These are useful for diagnosing operational friction and capacity constraints. They tell you nothing about whether the system is producing content that earns rankings, retains readers, or serves actual search intent. Quality metrics fill that gap. Search impressions per piece at 90 days post-publish is a reliable proxy for whether a piece is surfacing at all in Google’s index for relevant queries. Average position by content cluster — not individual article — tells you whether your topical authority is building. Return visit rate, while imperfect as a stand-alone metric, functions as a useful proxy for usefulness: readers who found what they needed come back. Editorial defect rate — the percentage of published pieces requiring post-publish corrections for factual errors, broken links, or intent misalignment — is the quality metric most teams don’t track, and arguably the most informative one.
The feedback loop is what makes measurement valuable. Google’s helpful content documentation asks directly: “Is the content mass-produced by or outsourced to a large number of creators, or spread across a large network of sites, so that individual pages or sites don’t get as much attention or care?” That question is a measurement instrument in itself. If your answer changes as you scale — if individual pages are getting less attention because output is growing — your measurement system should catch that before Google does.
Frequently Asked Questions
What is the difference between content scaling and programmatic SEO?
Content scaling is the operational system for expanding editorial production — research-driven, voice-consistent, intent-matched articles — without proportional increases in cost or quality loss. Programmatic SEO is a narrower strategy that scales pages using templates, structured data, and database-driven generation. The two overlap at the infrastructure layer but serve different purposes. Programmatic SEO can produce thousands of location pages or product variants from a template; content scaling produces editorial articles that require research, original analysis, and brand voice. Most niche sites need both at different stages — but conflating them leads to applying programmatic logic to editorial content, which is where quality degrades fast.
How do you scale content production without losing quality?
The reliable answer is: build the quality into the process before scaling the volume. A documented brief template that encodes search intent, required sources, editorial angle, and brand voice standards means the quality floor of every piece rises before writing begins. A structured review checklist — not a judgment call, but a named set of quality gates — means errors and thin content don’t make it through. And a measurement system that tracks quality metrics (not just volume metrics) catches degradation before it compounds. These three systems — brief, review, measurement — are the minimum viable infrastructure for scaling without quality loss.
At what point should a small content team start scaling output?
When you can answer yes to the scaling readiness checklist: you have a brief template, a named reviewer, a fact-checking process, and intent-driven topic selection already in place. Scaling before those systems exist just means compressing them under volume pressure — which is the Compression Cascade in practice. A team producing 6 well-researched, well-reviewed, genuinely useful articles a month has a stronger foundation for scaling than a team producing 20 thin ones. Get the system right at low volume, then increase velocity.
How can AI help with content scaling without producing generic output?
Position AI as infrastructure, not as the author. Use it for research synthesis (summarizing source sets, surfacing related questions, populating brief fields), first-draft scaffolding (structure and factual skeleton from a strong brief), and publishing-stage automation (formatting, metadata, scheduling). Keep intent interpretation, source credibility evaluation, claim verification, angle selection, and brand voice calibration with a human editor. The AI content editing pass — reviewing at the sentence level for accuracy, voice, and originality — is the judgment gate that separates AI-assisted scaling from AI slop.
How do you maintain brand voice when multiple people or AI tools are involved in production?
Brand voice is an upstream problem, not a downstream one. It should be encoded in the brief template — not as vague adjectives (“conversational but authoritative”) but as specific, example-driven guidance: sentence length preferences, vocabulary choices to use and avoid, structural patterns the brand favors, and the stance the brand takes on contested questions in the niche. When AI tools are involved, the brief is what constrains the output toward the brand voice. When multiple human contributors are involved, the brand voice guide — anchored to real examples from your best-performing content — is what makes the standard transferable without a senior editor reviewing every sentence.
What metrics actually tell you whether your content scaling strategy is working?
The metrics that matter most: search impressions per piece at 90 days post-publish (is it surfacing at all?), average position by content cluster (is topical authority building?), return visit rate as a usefulness proxy, and editorial defect rate (percentage of published pieces requiring post-publish corrections). Volume metrics — pieces published per month, total cycle time — tell you about operational friction, not content performance. Teams that optimize for volume metrics without tracking quality metrics are running a publishing schedule, not a scaling strategy.
What are the most common mistakes teams make when trying to scale content?
Setting a volume target before building the operational system that supports it. Treating AI output as review-ready rather than draft-ready. Letting brief quality degrade silently before draft quality degrades visibly. Measuring only volume (pieces published) and not quality (performance per piece). And automating judgment tasks — intent interpretation, claim verification, angle selection — because they’re time-consuming, rather than automating friction tasks because they’re mechanical. Every one of these mistakes follows a predictable pattern; they appear in the failure modes section of this article with their early warning signals.
How long does it take to build a repeatable content scaling system?
The honest answer: the brief template can be documented in a day, if you already have a body of content to model it on. The review checklist takes a week to design and another month to refine through use. The measurement system takes a full quarter to produce meaningful data. Most teams reach a functional Stage 2 operation — templated, brief-driven, with a basic review gate — within 60 to 90 days of deliberate investment. Stage 3 (workflow-automated) and Stage 4 (measured and optimized) take longer, but the compounding return on each stage makes the investment straightforward to justify.
Conclusion
Content scaling works when it is treated as an operational system — not a publishing target, not a tool decision, and not a headcount problem. The teams that scale successfully are the ones that encode editorial standards into the process before increasing velocity: a brief template that carries intent and voice, a review gate that protects judgment, and a measurement system that catches quality degradation before it shows up in traffic data. The two most actionable steps from this framework: identify your current stage using the maturity model before adding any speed to the system, and map your production tasks explicitly against the friction/judgment distinction before deciding what to automate. Then run the scaling readiness checklist. The first gate that’s missing from your current operation is where to start — everything else can wait.
References
External sources
- Creating Helpful, Reliable, People-First Content | Google Search Central | Documentation | Google for Developers — https://developers.google.com/search/docs/fundamentals/creating-helpful-content
- Google Search’s Guidance on Generative AI Content on Your Website | Google Search Central | Documentation | Google for Developers — https://developers.google.com/search/docs/fundamentals/using-gen-ai-content
- Spam Policies for Google Web Search | Google Search Central | Documentation | Google for Developers — https://developers.google.com/search/docs/essentials/spam-policies
- REST API Handbook | Developer.WordPress.org — https://developer.wordpress.org/rest-api/
Related content
- How to Scale a Niche Site With AI Content Without Killing Your Rankings — Contentosapp
- Programmatic Content: How to Scale Pages Without Repeating the Same Thin Template — Contentosapp
- Programmatic SEO With AI: How to Scale Content Without Triggering Google’s Spam Filters — Contentosapp
- How to Write SEO Articles With AI: The Complete Workflow That Actually Ranks — Contentosapp
- How to Make AI Content Rank: The Exact System That Works in 2026 — Contentosapp
- How to Edit AI Content: The Sentence-Level Pass That Makes It Rank — Contentosapp
- AI Content Case Study: 25 Articles in 25 Days on WordPress — Real Numbers at Day 25 — Contentosapp