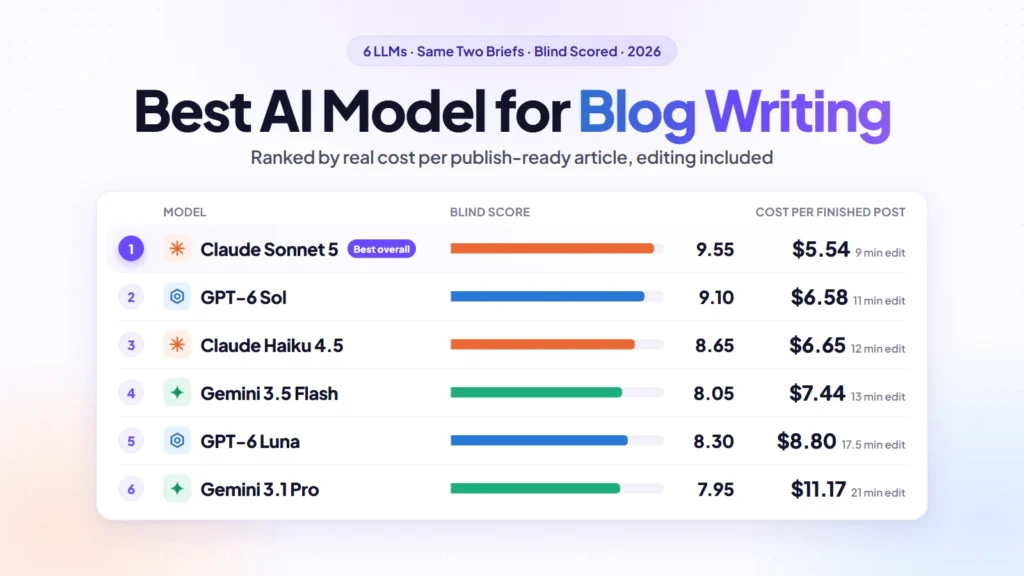
No model won every category, but Claude Sonnet 5 came closest to being the best AI model for blog writing in our test. We ran six large language models (LLMs) through the same two SEO briefs. Sonnet 5 had the highest blind reader score (9.55 out of 10), the fewest factual errors (1 in 20 checked claims) and the lowest real cost per publish-ready article: $5.54, once editing time is counted. It lost only on generation speed and raw API price.
GPT-6 Sol was the runner-up on quality. GPT-6 Luna had by far the smallest API bill, about $0.05 per article, yet it turned out to be one of the most expensive models to finish.
Most “best LLM for writing” and “best AI for writing” lists rank models from feature pages and a few chat prompts. We wanted numbers from the job bloggers actually do: turn a brief into a draft, then fix that draft until it’s ready to publish. So we kept the whole pipeline fixed, changed only the model and timed the cleanup.
One disclosure up front: the test ran inside Contentosapp Studio, the WordPress plugin this site publishes. This article was also drafted with it and then edited by a human. Every number below comes from those runs or from the vendors’ official pricing pages, checked September 28, 2026. We rechecked prices and model availability on November 16, 2026; what changed is listed under “What Changed Since the Test” below.
At a Glance: What the Test Showed
- Best prose and accuracy: Claude Sonnet 5 scored 9.55 out of 10 with blind readers, had all 10 checked citations supported and made 1 factual error in 20 checked claims.
- Best value: Sonnet 5 was also the cheapest per publish-ready article, at $5.54, because it needed only 9 minutes of editing. GPT-6 Sol ($6.58) and Claude Haiku 4.5 ($6.65) came next.
- Cheapest tokens, not cheapest posts: GPT-6 Luna has the lowest API price in the test, but its drafts needed 17.5 minutes of editing on average, for a real cost of $8.80 per article.
- Editing is the real bill: at $30 an hour, editing made up 81% to 99% of the total cost for every model. Gemini 3.1 Pro was the fastest to generate a draft and the slowest to fix one, at 21 minutes.
- Newer versions exist (November 2026): Claude Sonnet 5.5, Claude Haiku 5.5, GPT-6.1 Sol and the Gemini 4 family are now on the vendors’ price lists. A smaller follow-up test pitted Sonnet 5.5 against GPT-6.1 Sol (see “What Changed Since the Test”); the rest are untested, so this ranking covers the six versions named here.
How We Tested Six AI Models on the Same Two Briefs
Two briefs, six models, one pipeline. Each model wrote the same two articles: “how to grow tomatoes in containers,” a practical how-to, and “how to choose a standing desk,” a buying guide. Everything except the model stayed fixed: the Contentosapp Studio seven-agent workflow, the system prompts, the web search provider, the brand voice and the settings. Images were off, and every run ended as a draft.
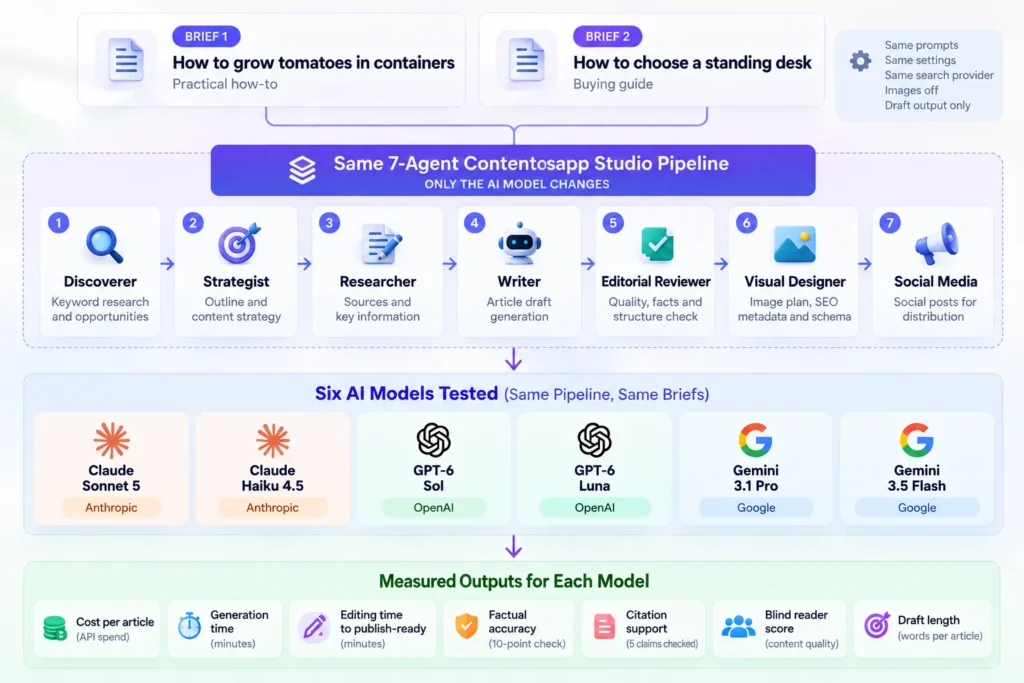
The six models were Claude Sonnet 5 and Claude Haiku 4.5 from Anthropic, GPT-6 Sol and GPT-6 Luna from OpenAI, and Gemini 3.1 Pro and Gemini 3.5 Flash from Google. That gave us 12 drafts. We scored every draft before anyone edited it, then timed the edit.
| What we measured | How we measured it |
|---|---|
| API cost per article | Cost of all seven agent calls behind one draft |
| Generation time | From the start of the run to the finished draft |
| Blind reader score | Readers scored each draft from 1 to 10 without knowing which model wrote it |
| Citations supported | Five cited claims per draft, each checked against the page it links to |
| Factual errors | Ten verifiable claims per draft (numbers, dates, specs), checked against reliable sources |
| Editing time | Minutes a human editor needed to make the draft ready to publish |
| Studio reviewer | Highest severity flagged by the plugin’s built-in editorial reviewer (minor, major or critical) |
This was an API test with fixed prompts. Claude.ai, ChatGPT and the Gemini app wrap the same models in their own instructions, so results there can differ. If you write inside a chat app, treat these numbers as a guide, not a forecast.
Test limitations. Two briefs per model is a small sample. We used one pipeline with its default prompts, and model versions change fast, so a different prompt setup could shift the ranking. Read this as evidence from a real production workflow, not a lab benchmark. For a longer run with the same plugin, see our 25-article case study on WordPress.
The Results: Six LLMs Side by Side
Here is how each model performed, averaged across both briefs. The best result in each column is in bold.
| Model | API cost per article | Generation time | Blind score (of 10) | Citations supported | Factual errors | Editing time |
|---|---|---|---|---|---|---|
| Claude Sonnet 5 | $1.04 | 13m 09s | 9.55 | 10 of 10 | 1 of 20 | 9 min |
| Claude Haiku 4.5 | $0.65 | 9m 33s | 8.65 | 8 of 10 | 3 of 20 | 12 min |
| GPT-6 Sol | $1.08 | 7m 48s | 9.10 | 9 of 10 | 3 of 20 | 11 min |
| GPT-6 Luna | $0.05* | 6m 23s | 8.30 | 7 of 10 | 5 of 20 | 17.5 min |
| Gemini 3.1 Pro | $0.67 | 5m 05s | 7.95 | 7 of 10 | 6 of 20 | 21 min |
| Gemini 3.5 Flash | $0.94 | 5m 37s | 8.05 | 7 of 10 | 5 of 20 | 13 min |
*GPT-6 Luna’s API cost is an estimate. The cost recorded in our runs ($0.70 and $0.84) didn’t match Luna’s token prices, so we recalculated it from GPT-6 Sol’s measured cost at Luna’s rates, which are exactly 1/20 of Sol’s for both input and output. That assumes a similar token count per run. Luna wrote about 18% fewer words than Sol, so its real cost may be slightly lower.
Sonnet 5 led every quality column. GPT-6 Sol was the only other model to average above 9 with readers. And the fastest models were not the cheapest to finish: Gemini 3.1 Pro produced a draft in about five minutes, then needed more editing than any other model.
The Studio’s automated reviewer found no critical issue in any of the 12 drafts. It flagged at least one major issue in three of them: Claude Haiku 4.5 and GPT-6 Luna on the tomato brief, and Gemini 3.1 Pro on the desk brief.
Length varied more than you’d expect from identical briefs. GPT-6 Sol wrote the longest drafts, 2,841 words on average, about 46% more than Gemini 3.5 Flash (1,941). GPT-6 Luna was the least consistent, with 2,123 words on one brief and 2,543 on the other. Sonnet 5 stayed within 77 words across both. Extra length didn’t cost Sol much editing time, but Luna’s swings came with the second-longest edits in the test.
Official API pricing and specs
| Model | Input / output per 1M tokens | Long-context price | Context window | Knowledge cutoff |
|---|---|---|---|---|
| Claude Sonnet 5 | $2.00 / $10.00 | Same rate across the full 1M | 1M tokens | Jan 2026 |
| Claude Haiku 4.5 | $1.00 / $5.00 | — | 200K tokens | Feb 2025 |
| GPT-6 Sol | $2.00 / $10.00 | $4.00 / $15.00 | 1.05M tokens | Apr 20, 2026 |
| GPT-6 Luna | $0.10 / $0.50 | $0.20 / $0.75 | 1.05M tokens | May 18, 2026 |
| Gemini 3.1 Pro (Preview) | $2.00 / $12.00 | $4.00 / $18.00 above 200K | Not confirmed | Not confirmed |
| Gemini 3.5 Flash | $1.50 / $9.00 | Same rate above 200K | Not confirmed | Not confirmed |
Prices come from the official Anthropic, OpenAI and Google Cloud pricing pages, checked September 28, 2026. Google lists the Pro model as “Gemini 3.1 Pro Preview,” so its price and availability can still change. We could not confirm the Gemini context windows or knowledge cutoffs on the pages we checked. On a recheck on November 16, 2026, the Claude and GPT-6 prices in this table were unchanged, and Gemini 3.1 Pro was still a preview at the same price on Google’s Gemini API pricing page, which no longer lists Gemini 3.5 Flash.
What a Publish-Ready Article Actually Costs
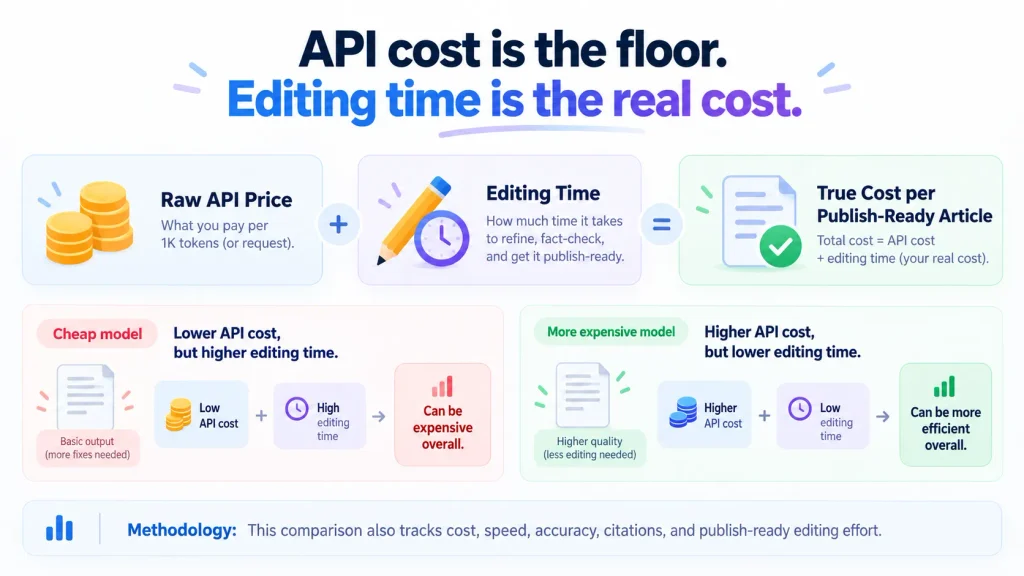
The API price is the number everyone compares. It’s also the smallest part of the bill. The real cost of a finished post is API cost + (editing minutes ÷ 60) × your hourly rate. We valued editing time at $30 an hour.
| Model | API cost | Editing time | Editing cost at $30/hr | Total per publish-ready article |
|---|---|---|---|---|
| Claude Sonnet 5 | $1.04 | 9 min | $4.50 | $5.54 |
| GPT-6 Sol | $1.08 | 11 min | $5.50 | $6.58 |
| Claude Haiku 4.5 | $0.65 | 12 min | $6.00 | $6.65 |
| Gemini 3.5 Flash | $0.94 | 13 min | $6.50 | $7.44 |
| GPT-6 Luna | $0.05* | 17.5 min | $8.75 | $8.80 |
| Gemini 3.1 Pro | $0.67 | 21 min | $10.50 | $11.17 |
Real cost per publish-ready article
API costEditing at $30/hr
Editing made up 81% to 99% of the total for every model. That flips the usual advice. GPT-6 Luna costs 20 times less than Sonnet 5 per token, yet a finished Luna article came to $8.80 against $5.54 for Sonnet, because Luna’s drafts took almost twice as long to fix. Swap in your own hourly rate and the leader holds: Sonnet 5 stays the cheapest per finished post at any editing rate above about $8 an hour.
Per-token prices mislead for a second reason. According to Anthropic, Claude models from Opus 4.7 onward use a newer tokenizer that produces roughly 30% more tokens for the same text. Comparing rate cards across vendors, or even across Claude generations, isn’t comparing like with like. Measuring cost per article avoids that problem.
If you’re weighing this against a subscription tool, our breakdown of AI content cost per article adds seat fees and word caps to the same math. And if you’d rather pay the provider directly, a BYOK AI writer keeps the API part of the bill at the provider’s own price.
Model-by-Model Results
Claude Sonnet 5
Sonnet 5 was the strongest writer in the test. Readers gave it 9.7 on the tomato brief and 9.4 on the desk brief, the two highest scores of all 12 drafts. All ten checked citations held up, and its desk draft had zero errors in ten checked claims. Editing took 10 and 8 minutes.
The trade-off is speed. At about 13 minutes per draft, it was the slowest model here, more than twice as slow as either Gemini model. For a draft you don’t have to watch, that rarely matters. Anthropic charges $2 input and $10 output per million tokens, and that is now the standard rate: the increase to $3/$15 scheduled for September 1, 2026 was canceled. Sonnet 5 also bills its full 1M-token context at that rate, with no long-context surcharge. Since our test, Anthropic has released Claude Sonnet 5.5 at the same $2/$10. We tested Sonnet 5, which is still an active model.
Claude Haiku 4.5
Haiku 4.5 was the cheapest Claude model to run, at $0.65 per article on average. Quality landed mid-table: a blind score of 8.65, 8 of 10 citations supported and 3 errors in 20 claims. Editing took 12 minutes on both briefs, which made it the most predictable model to clean up.
Two caveats. Its reliable knowledge ends in February 2025, the oldest cutoff among the models we could confirm, so recent topics need extra checking. And it is now the previous generation. Anthropic has released Claude Haiku 5.5, priced from $0.10 input and $0.50 output per million tokens for prompts up to 100,000 tokens, a tenth of Haiku 4.5’s rate. On Anthropic’s model deprecations page, Haiku 4.5 was still active on November 16, 2026, but the date it was guaranteed through (“not sooner than October 15, 2026”) has passed. Check its status before you build a workflow around it. We haven’t tested Haiku 5.5.
GPT-6 Sol
Sol was the runner-up almost everywhere: 9.10 with blind readers, 9 of 10 citations supported, 3 errors in 20 claims and 11 minutes of editing. Its tomato draft needed only 9 minutes, the least of any draft on that brief. It also wrote the most, about 14% more words than Sonnet 5, and finished in under 8 minutes.
At $2/$10 per million tokens, Sol costs the same as Sonnet 5 on standard requests, but OpenAI’s long-context rate rises to $4/$15. Its knowledge cutoff is April 20, 2026, three months newer than Sonnet 5’s, which helps on fast-moving topics. OpenAI’s price list now also includes GPT-6.1 Sol at the same $2/$10. We tested GPT-6 Sol.
GPT-6 Luna
On paper, Luna is the bargain: $0.10 input and $0.50 output per million tokens, 20 times below Sol, which puts its API bill at about $0.05 per article (estimated, see the note under the results table). Once editing time is counted, that advantage disappears. Its drafts averaged 8.30 with readers, 7 of 10 citations held up, and its tomato draft had 3 errors in 10 claims, the most on that brief. Editing took 20 and 15 minutes, for a real cost of $8.80 per article.
Luna does have the most recent knowledge cutoff among the models we could confirm, May 18, 2026. If you publish at high volume and accept heavier edits, OpenAI’s batch rate lowers it further, to $0.05 input and $0.25 output.
Gemini 3.1 Pro
Gemini 3.1 Pro was the fastest writer, at about 5 minutes per draft, and one of the cheapest to run, at $0.67. It was also the hardest to fix. Its desk draft took 32 minutes of editing, had 4 errors in 10 checked claims and only 3 of 5 citations held up. That single draft was the weakest result in the test.
On the tomato brief it did fine: 10 minutes of editing and 2 errors. Google lists it as “Gemini 3.1 Pro Preview” on its pricing page, at $2/$12 per million tokens ($4/$18 above 200K tokens), so price and availability can still change.
Gemini 3.5 Flash
Flash sat in the middle: a blind score of 8.05, 7 of 10 citations supported, 5 errors in 20 claims and 13 minutes of editing, for $7.44 per finished article. It wrote the shortest drafts, 1,941 words on average.
Know this before you choose it: Google has since released Gemini 3.8 Flash, priced at $0.75 input and $3.75 output per million tokens through December 31, 2026, and $1.50/$7.50 from January 1, 2027. We tested 3.5 Flash, at $1.50/$9, so treat these results as a baseline for the newer model, not a verdict on it. As of November 16, 2026, Google’s Gemini API pricing page no longer lists Gemini 3.5 Flash, so confirm it is still available to you before you choose it.
Tomatoes vs. Standing Desk: How the Brief Changed the Results
The buying guide was harder on average. Across the six models, the desk drafts needed 16 minutes of editing against 11.8 for the tomato drafts, and they had 13 factual errors in 60 checked claims against 10.
Most of that gap came from one draft. Without Gemini 3.1 Pro’s 32-minute desk article, the desk average drops to 12.8 minutes, close to the tomato average. Product advice is where weak drafts get expensive: specs, sizes and price ranges are easy to state wrongly and slow to check.
So match the ranking to what you publish. If most of your posts are buying guides, weigh the factual-error and citation columns more heavily than the blind score. If you mostly publish how-tos, the editing gap between models is smaller: 9 to 20 minutes on the tomato brief, against 8 to 32 on the desk brief.
What Changed Since the Test (November 2026 Update)
We ran the test in September 2026 and rechecked the vendors’ pages on November 16, 2026. The prices of the models we tested haven’t changed, but every vendor now lists newer models next to them. None of the newer ones was part of this test.
| Model we tested | Status on November 16, 2026 | Newer model now listed |
|---|---|---|
| Claude Sonnet 5 | Active, still $2/$10. Anthropic lists its retirement as “not sooner than June 30, 2027.” | Claude Sonnet 5.5, also $2/$10 (follow-up test below) |
| Claude Haiku 4.5 | Active, still $1/$5. The date it was guaranteed through (“not sooner than October 15, 2026”) has passed. | Claude Haiku 5.5, from $0.10/$0.50 for prompts up to 100,000 tokens |
| GPT-6 Sol | Still on OpenAI’s price list at $2/$10 | GPT-6.1 Sol, also $2/$10 (follow-up test below) |
| GPT-6 Luna | Still on OpenAI’s price list at $0.10/$0.50 | No newer Luna listed |
| Gemini 3.1 Pro | Still labelled “Preview,” at $2/$12 | Gemini 4 family: Carbon, Argon and Hydrogen |
| Gemini 3.5 Flash | No longer on Google’s Gemini API pricing page | Gemini 3.6 Flash and Gemini 3.8 Flash ($0.75/$3.75 through December 31, 2026) |
Prices are input/output per million tokens, from the Anthropic pricing, Anthropic model deprecations, OpenAI pricing and Gemini API pricing pages.
So read the ranking as a description of the six versions we ran, not of their successors. Where the newer model costs the same as the one we tested, as Claude Sonnet 5.5 and GPT-6.1 Sol do, it is the natural one to try first. Run it on one of your own briefs and time the edit before you switch: a new version can change draft length, accuracy and editing time in either direction.
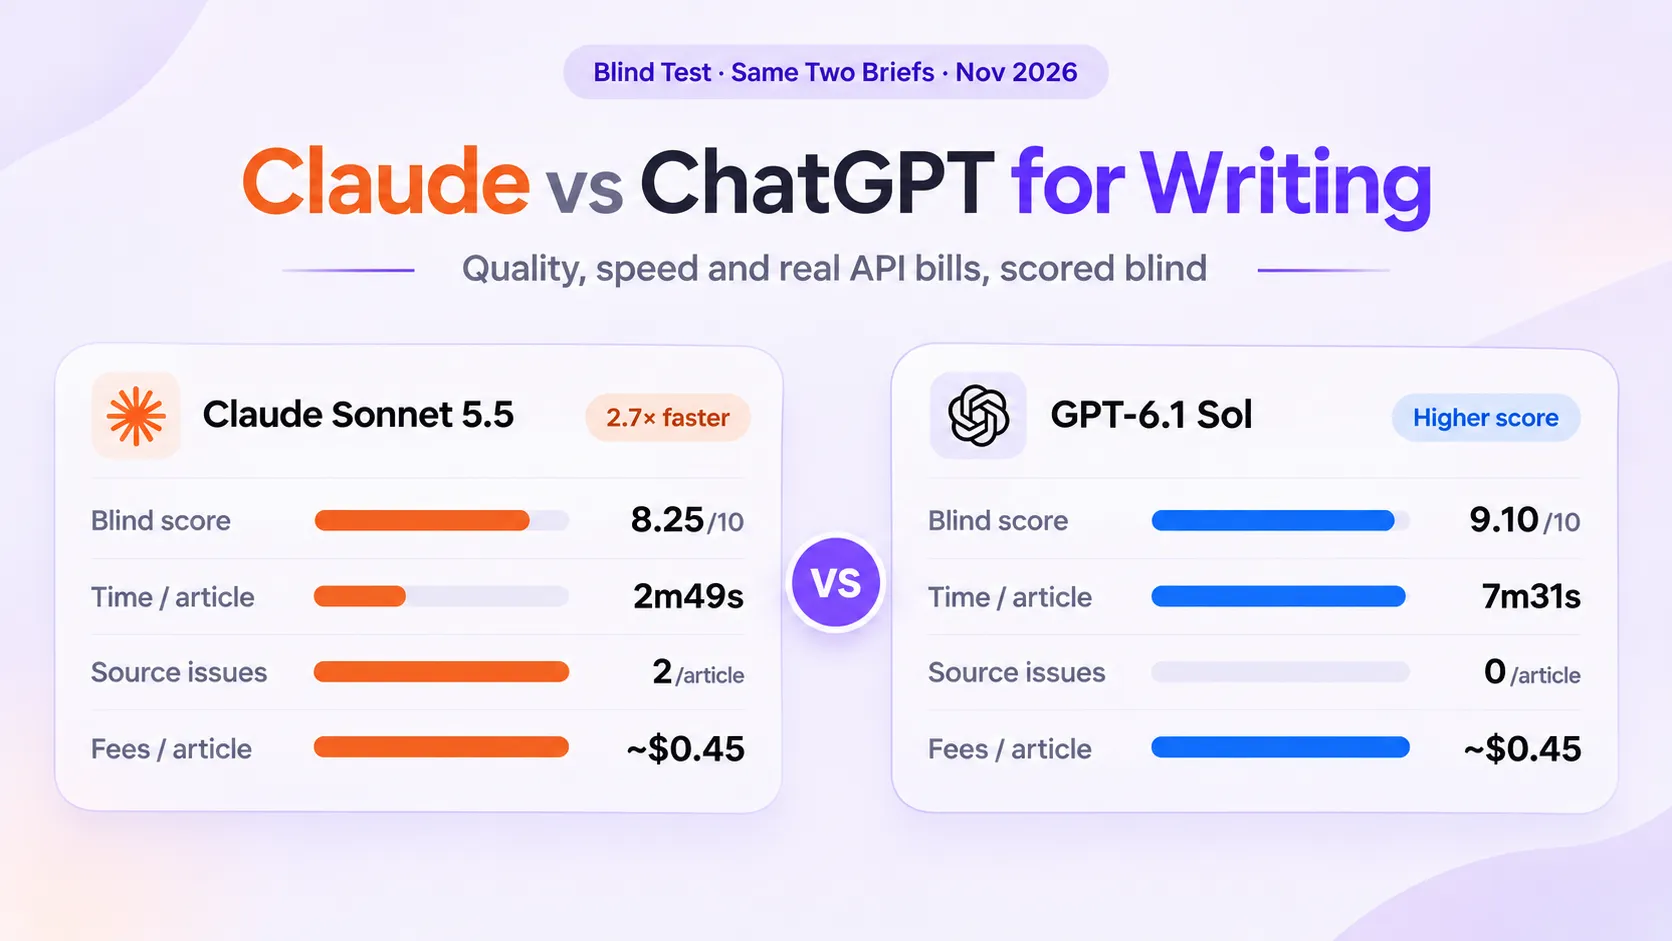
Follow-up test (November 17, 2026): we ran Claude Sonnet 5.5 and GPT-6.1 Sol through the same seven-agent pipeline on two new personal finance briefs and scored the drafts blind. GPT-6.1 Sol scored higher (9.10 vs. 8.25 on average), Sonnet 5.5 finished about 2.7 times faster, and model fees tied at about $0.45 per article. That is the reverse of their predecessors’ order here, but the briefs were different and we didn’t time the editing, so it doesn’t replace this ranking. Full results: Claude vs ChatGPT for writing, a blind test of Sonnet 5.5 and GPT-6.1 Sol.
Best AI Model for Blog Writing by Use Case
No single model led every criterion, so the right pick depends on what you optimize for.
Best prose and accuracy: Claude Sonnet 5. Highest blind score (9.55), every checked citation supported and 1 factual error in 20 claims. Pick it when your name is on the byline.
Best value per finished post: Claude Sonnet 5. $5.54 per publish-ready article at $30 an hour, and still the cheapest at any editing rate above about $8 an hour. GPT-6 Sol ($6.58) is the runner-up if you already work with OpenAI.
Lowest API bill: GPT-6 Luna. About $0.05 per article in API fees, the cheapest by far, but plan for 15 to 20 minutes of editing per draft. For better drafts on a small budget, Claude Haiku 4.5 ($0.65) needed less editing. It is now the previous-generation Haiku, and the date Anthropic guaranteed it through (October 15, 2026) has passed, so check its status first. Its successor, Claude Haiku 5.5, costs a tenth as much per token; we haven’t tested it.
Research-heavy posts: Claude Sonnet 5, then GPT-6 Sol. They had 10 and 9 of 10 checked citations supported. If your topics are very recent, Sol’s April 2026 knowledge cutoff is newer than Sonnet 5’s January 2026.
Fastest drafts: Gemini 3.1 Pro. About 5 minutes per draft, but budget time to fix it, especially on product-heavy topics.
Once you’ve picked a model, here’s how to use your own AI API key in WordPress.
Best LLM for Writing: How Far These Results Go Beyond Blog Posts
If you’re looking for the best LLM for writing in general, or the best AI model for writing anything from guides to newsletters, this test answers part of the question. It measured one kind of writing: researched, long-form articles of about 1,900 to 2,900 words, generated from an SEO brief through the API.
Where the ranking should hold. Other researched non-fiction asks for the same things we scored: citations that support the claim, few factual errors and a draft that needs little editing. For guides, newsletters, documentation and product content, we’d start with the same two models, Claude Sonnet 5 and GPT-6 Sol. That is an inference from this test, not something we measured.
Where it doesn’t apply. We didn’t test fiction, poetry, academic essays or short social copy. Voice, plot and argument weren’t scored, and following a brief precisely is a different skill from telling a story. Don’t use this table to choose a model for a novel.
For long-form content writing, this is the full ranking by real cost per publish-ready article, with editing valued at $30 an hour:
- Claude Sonnet 5: $5.54 per publish-ready article, blind reader score 9.55
- GPT-6 Sol: $6.58 per publish-ready article, blind reader score 9.10
- Claude Haiku 4.5: $6.65 per publish-ready article, blind reader score 8.65
- Gemini 3.5 Flash: $7.44 per publish-ready article, blind reader score 8.05
- GPT-6 Luna: $8.80 per publish-ready article, blind reader score 8.30
- Gemini 3.1 Pro: $11.17 per publish-ready article, blind reader score 7.95
Frequently Asked Questions
What is the best LLM for writing blog posts?
In our test, Claude Sonnet 5. It had the highest blind reader score (9.55 out of 10), the fewest factual errors (1 in 20 checked claims) and the lowest cost per publish-ready article ($5.54 with editing at $30 an hour). GPT-6 Sol was second on all three. Newer versions of both have been released since the test and aren’t covered by it.
Is Claude better than ChatGPT for blog writing?
In our test, yes, by a small margin. Claude Sonnet 5 beat GPT-6 Sol on blind reader score (9.55 vs. 9.10), citations (10 vs. 9 of 10), factual errors (1 vs. 3 in 20) and editing time (9 vs. 11 minutes). Both cost $2/$10 per million tokens. This was an API test with fixed prompts, so Claude.ai and ChatGPT may behave differently. The newer versions came out the other way: in a smaller follow-up on two finance briefs, GPT-6.1 Sol’s drafts scored 9.10 against 8.25 for Claude Sonnet 5.5. The newer versions came out the other way: in a smaller follow-up on two finance briefs, GPT-6.1 Sol’s drafts scored 9.10 against 8.25 for Claude Sonnet 5.5. See our Claude vs ChatGPT for writing test.
Claude vs. Gemini for writing: which is more accurate?
Claude, in our runs. Sonnet 5 made 1 factual error in 20 checked claims and Haiku 4.5 made 3, against 6 for Gemini 3.1 Pro and 5 for Gemini 3.5 Flash. Citations followed the same pattern: 10 and 8 of 10 supported for the Claude models, 7 of 10 for both Gemini models.
Gemini vs. ChatGPT for writing: which is better?
GPT-6 Sol beat both Gemini models on every quality measure we took, with a blind score of 9.10 against 7.95 and 8.05. The Gemini models were faster, at about 5 minutes per draft against Sol’s 8, but their drafts needed more editing.
Which ChatGPT model is best for writing?
Of the two OpenAI models we tested through the API, GPT-6 Sol. It scored 9.10 with blind readers against 8.30 for GPT-6 Luna, made 3 factual errors in 20 checked claims against 5 and needed 11 minutes of editing against 17.5. Luna’s API bill is about 20 times smaller, but its finished articles cost more: $8.80 against $6.58. The ChatGPT app wraps these models in its own instructions, so results there can differ.
Which AI model is cheapest per blog post?
It depends on what you count. GPT-6 Luna had the lowest API cost, about $0.05 per article. With editing time at $30 an hour, Claude Sonnet 5 was the cheapest at $5.54 per publish-ready post, while Luna came to $8.80.
How much does it cost to write a blog post with your own API key?
In our test, the API cost of one full seven-agent article ranged from about $0.05 with GPT-6 Luna to $1.17 with Claude Sonnet 5 and GPT-6 Sol, depending on the brief. Editing is the bigger number: 8 to 32 minutes per draft, or $4 to $16 at $30 an hour. Our AI content cost per article guide compares this with subscription tools.
What is the best free AI for blog writing?
None of the models in this test is free through the API; all six bill per token. Free chat plans are a different setup, with usage caps and no control over the system prompt, so these results don’t transfer directly. If you want low cost rather than zero cost, the cheapest drafts in our test, from GPT-6 Luna, cost about $0.05 each in API fees.
What to Do With These Results
The biggest difference between these six models wasn’t the API bill. It was the 12 minutes of editing that separated the easiest model to finish from the hardest.
Your next step: pick the two or three models that fit your use case and run the math with your own hourly rate: API cost + (editing minutes ÷ 60) × hourly rate. The lowest total that still clears your quality bar is the model worth putting an API key behind.
Raw Results: All 12 Drafts
| Model | Brief | API cost | Time | Words | Studio reviewer | Citations (of 5) | Errors (of 10) | Editing | Blind score |
|---|---|---|---|---|---|---|---|---|---|
| Claude Sonnet 5 | Tomatoes | $0.91 | 12m 32s | 2,456 | Minor only | 5 | 1 | 10 min | 9.7 |
| Claude Sonnet 5 | Desk | $1.17 | 13m 46s | 2,533 | Minor only | 5 | 0 | 8 min | 9.4 |
| Claude Haiku 4.5 | Tomatoes | $0.54 | 9m 12s | 2,232 | Major | 4 | 1 | 12 min | 8.6 |
| Claude Haiku 4.5 | Desk | $0.76 | 9m 54s | 2,355 | Minor only | 4 | 2 | 12 min | 8.7 |
| GPT-6 Sol | Tomatoes | $0.99 | 7m 37s | 2,789 | Minor only | 5 | 1 | 9 min | 9.2 |
| GPT-6 Sol | Desk | $1.17 | 7m 59s | 2,893 | Minor only | 4 | 2 | 13 min | 9.0 |
| GPT-6 Luna | Tomatoes | $0.05* | 6m 10s | 2,123 | Major | 3 | 3 | 20 min | 8.4 |
| GPT-6 Luna | Desk | $0.06* | 6m 35s | 2,543 | Minor only | 4 | 2 | 15 min | 8.2 |
| Gemini 3.1 Pro | Tomatoes | $0.60 | 4m 56s | 1,989 | Minor only | 4 | 2 | 10 min | 8.1 |
| Gemini 3.1 Pro | Desk | $0.73 | 5m 13s | 2,090 | Major | 3 | 4 | 32 min | 7.8 |
| Gemini 3.5 Flash | Tomatoes | $0.90 | 5m 33s | 1,890 | Minor only | 4 | 2 | 10 min | 7.9 |
| Gemini 3.5 Flash | Desk | $0.98 | 5m 40s | 1,992 | Minor only | 3 | 3 | 16 min | 8.2 |
*Estimated from GPT-6 Sol’s measured cost at Luna’s token rates (1/20 of Sol’s). See the note under the results table.
Sources
Anthropic: Claude API pricing
Anthropic: Claude models overview
OpenAI: API pricing
OpenAI: Models
Google Cloud: Agent Platform pricing
Anthropic: Model deprecations
Google: Gemini API pricing
All pages checked September 28, 2026. The Anthropic pricing and deprecations pages, the OpenAI pricing page and the Gemini API pricing page were rechecked November 16, 2026.